torchiaf's PR, reviewed twice at 79968cc: Cody's process (in this session) and ours (a fresh agent that didn't see the first), then merged and re-checked. Nothing was posted to GitHub.
Preview:rancheraipr346r, built from 79968cc, backend 13.62 (torchiaf's AI Rancher, v2.15.1): its agent is a local build with /v1/api/chats/{id}/usage and llm-mock v1.2.3, planning off. Baseline: rancher-ai-main at 28ae86d (rebuilt today by another session), backend mf, whose AI agent is evicted, so the baseline only shows the footer, not a working chat.
Where it stands: works with the new agent; merge it after agent PR 507, and fix how failures and source names show
On a running build against an agent that has the endpoint, everything the PR describes works: the count appears after the welcome message (0, then 1.8K), refreshes after each answer (8.5K), matches the API to the token, resets on New chat, follows the chat when you open one from History, and survives closing the panel. It holds at a 250px panel and in dark.
What I'd raise, in order: 1 the new spec can't pass before agent PR 507 merges, and its exact counts will break on agent prompt changes; 2 any failed request shows "Tokens used: 0", even over a count it already had; 3 By Source shows raw ids because its label keys aren't in this PR; 4 the button's accessible name has no "tokens". Then three optional cleanups (5). Suggested as a Comment review, not Request changes: the merge order is something torchiaf already knows, since he wrote both PRs.
The main flow live against the API (welcome, prompt, new chat, history, reopen), a stubbed 404, the raw source labels, the trigger's accessible name, the design screenshot, a long agent name truncating the number, and the CI tabulation (scroll test also red on main).
Same.
Only one pass did
Before/after demo videos. A sourced acceptance table (issue + ux 559). The llm-mock source showing counts are len(body)/4, so the spec's numbers depend on the agent's prompts. His a11y probe: contrast clean in both themes, target size within the spacing rule, Escape and aria-required-children on the popover (both already on main). A 250 and 320px panel.
A 500 after a shown count (wipes it to 0). A 7s-delayed response arriving after New chat (the guard works). A scratch jest test against the real en-us.yaml (the unit test mocks the missing key). The unused emit and prop, the untested fetchUsage, PR 507 making chatId required, the 19px taller console, a coverage grid.
Missed
The 500-after-a-count case (same cause as its 404 finding). The unit test that hides finding 3.
That the spec's exact counts come from other repos' prompts. The pre-existing popover issues (out of scope anyway).
CI deploys rancher-ai-agent from main (.github/scripts/deploy-rancher-ai.sh clones it with no ref). Main's app/routers/chat.py has no usage route; PR 507's head adds @router.get("/chats/{chat_id}/usage"). So every usage call 404s, the label stays " 0 ", and the spec fails all 3 attempts in both runs since it was added (43471969845, 43834164964). The description doesn't mention the dependency.
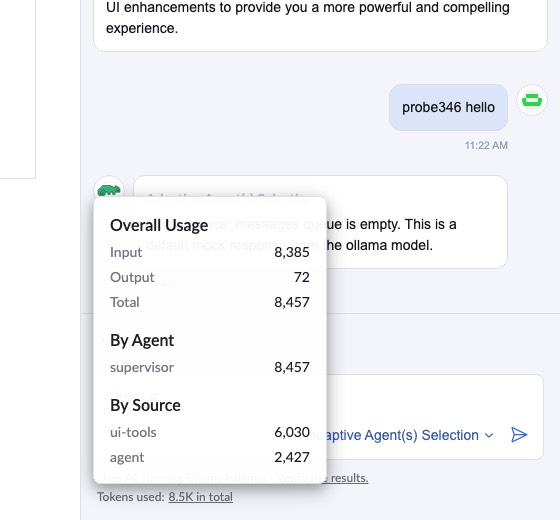
Separately (Pass A only): llm-mock 1.2.3 computes input = (len(request body)+3)/4 (internal/handlers/models/usage.go). The body is the agent's system prompt, the MCP tool schemas and the page context, so assertions like 1,747, 8,384 and 41,690 change when anyone edits a prompt in the agent repo. Live with default mock replies I got 1,747 / 24 for the welcome and 8,385 / 72 after one prompt, where the spec expects 25 and 8,384, because its queued replies differ slightly.
2
A failed usage request shows "Tokens used: 0", even over a count it had
fetchChatUsage turns every failure into null, fetchUsage writes it over the current value, and TokenUsage renders null as 0 with the button disabled. I re-checked Pass B's case: a real 1.8K, then a stubbed 500 on the refresh after a prompt, and the footer reads "Tokens used: 0", disabled. With a stubbed 404 on every call (an agent without the endpoint) it stays at 0 for the whole chat and logs "Failed to fetch chat usage" after each answer. Note PR 507 itself answers 404 for a chat with no recorded usage.
After a 500 on the refresh (stubbed): the 1.8K is gone.Every usage call 404 (stubbed), after a prompt.
3
By Source shows raw ids: the label keys aren't in this PR
sourceLabel looks up aiConfig.form.section.usage.sources.*. Those keys exist only on torchiaf's bu-feature-token-consumption branch, with the settings Usage page this PR left out, so every source shows its backend id: ui-tools, agent, planner, summarization. The design has "UI Tools" and "Planner". The unit test mocks the planner key into both t and i18n/exists, so it passes; Pass B's scratch test against the real en-us.yaml gets the raw ids back. The e2e asserts the raw ui-tools.
Same family, your call whether to add it: By Agent shows supervisor. In a single-agent chat all usage lands there, since PR 507 credits the orchestrator as supervisor and agentLabel only knows real agents. The issue's example calls it "Liz (General)"; the design shows only named agents. Pass B kept this as look-only, Pass A filed it; I left it out of the suggested text.
PR, after one prompt: supervisor, ui-tools, agent.Design (rancher/ux 559 screenshot).
4
The count's button is named "1.8K in total", with nothing about tokens
"Tokens used:" is a plain span next to the button and isn't linked to it. Tabbing from the prompt goes agent select, "Verify the results.", then "1.8K in total" (menu button), so a screen-reader user hears a number and no subject. The neighbouring "Verify the results." makes sense on its own. WCAG 2.4.6 / 1.3.1; a usability risk more than a strict failure.
'fetch:usage' is declared in Console's emits and nothing emits or listens to it. TokenUsage's disabled prop has no caller. fetchUsage (the reset, the guard for a chat the user left) has no unit test; the composable's test only gained the error log mock. Pass B checked the guard live: a response delayed 7s arrived after New chat and was ignored. Cody's no-nit rule drops these; ours keeps them, marked optional.
Enter opens the token popover; Escape leaves it open with aria-expanded="true". Its content sits in RcDropdown's role="menu" with no menu items (axe aria-required-children, critical). Both come from the existing TextLabel popover and show the same on "Verify the results.", so they're not this PR's. Worth an issue of its own if you want.
For the designer, not in the review
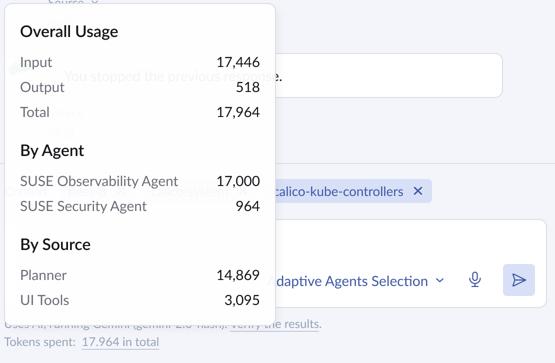
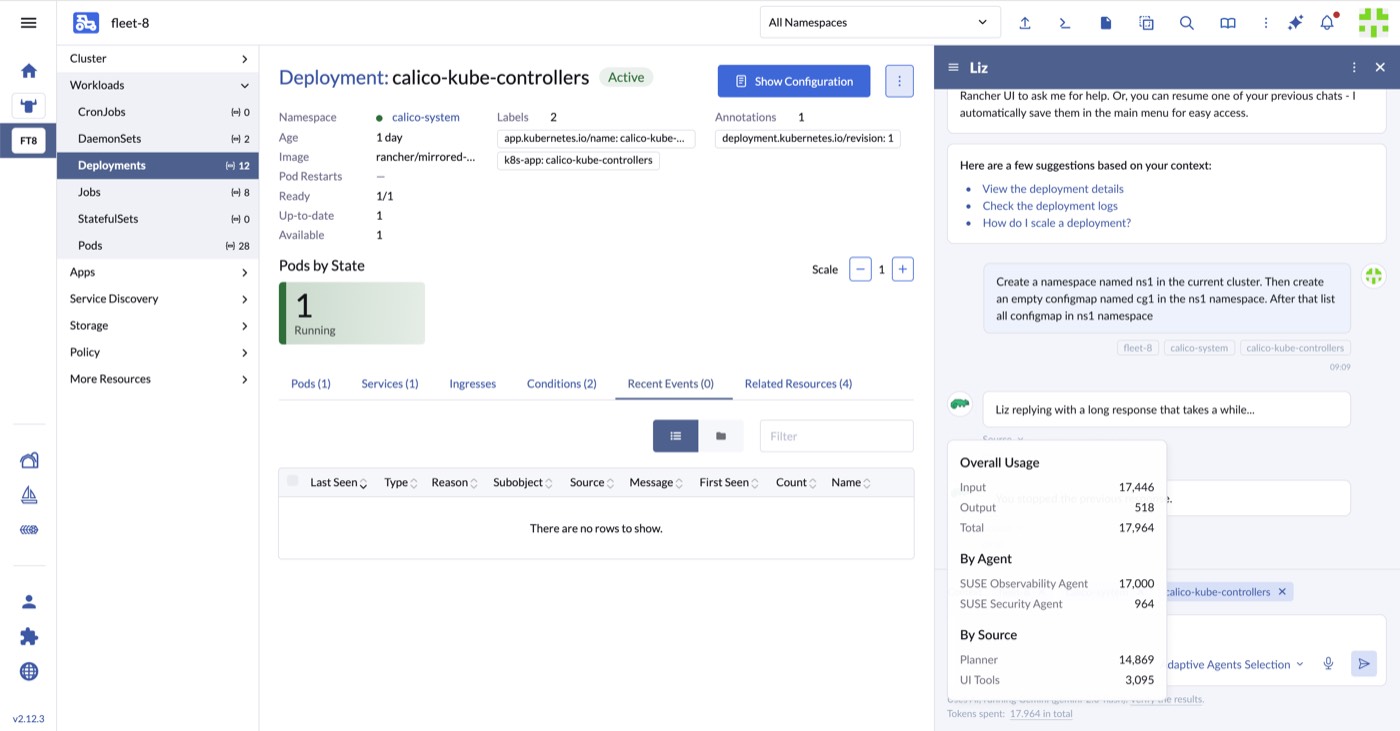
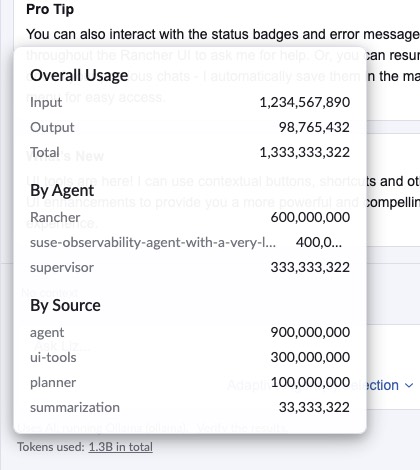
From rancher/ux 559 (the Figma API token has expired, so this is against the screenshot on that issue): the footer reads "Tokens spent: 17,964 in total", the exact number like the popover; the PR reads "Tokens used: 8.5K in total", compact on purpose (its code comment says so). The design's By Agent has only named agents, no supervisor. Section titles and row sizes match. Both passes also saw a long agent name squeeze the number to "400,0…" or "34,5…" (stubbed names; the full value is in the tooltip). The extra footer line makes the console 19px taller, which the design also does.
PR title typo: "consumtion". It becomes the squash commit subject.
Design, rancher/ux 559.PR with a stubbed long agent name: the value is cut.
Pass A: Cody's process
Followed my-pr-full-review from codyrancher/ai-skills at c04c11a, mapped to our setup: the PR preview for his dev server, rancher-ai-main for his master build, 13.62 behind the PR, local files instead of his harness, our recorder for the demos. It ran in this session (the passes in his table order, each written up on its own). His a11y probe ran from the clone against a Chromium with a CDP port.
Before this change: main.With this change: the PR.
Acceptance, from issue 189, its comments and rancher/ux 559
Criterion (source)
Verdict
AC1
Input, output and total shown (issue: "Capture input, output, and total token counts")
Met
AC2
Updates after every interaction, welcome and sub-agents included (issue: "for every interaction")
Met; sub-agent attribution only with a stubbed body
AC3
Per-agent breakdown, Liz and each agent by name (issue: "Liz (General): 850 tokens")
Partly met: label, number format, source names, supervisor row
AC5
New chat resets; an old chat shows its own count (implied)
Met
AC6
Console still works, light/dark/narrow (implied)
Met
-
Per-turn count under each answer (issue user flow) vs per-chat footer (design)
Open question; the later design was graded
Base review: findings 1, 2, 3.
Simplify: already simple; the unused emit and prop are nits.
Side effects: the renamed .chat-input-wrapper has no other users; the llm-info test id still wraps the same text for its page object; chatId on /complete/ui-tools has one caller; one more GET per answer; the footer row is 19px.
Component reuse: TokenUsage reuses the TextLabel popover; justified.
Accessibility: finding 4; finding 7 removed as already on main.
Verify, refine, condense, remove-suggestions, preexisting: 5 comments survived; 3 popover items removed as already on main.
Pass B: our process
A fresh agent that didn't see Pass A, following prompts/code-review.prompt.md and your review rules. Verdict: Request changes, for the CI dependency.
Live: the main flow, history, reopen, Enter and Space on both footer popovers, Tab order, and stubbed 500, 404, delayed and large multi-agent responses.
Tests: both touched suites pass (95 tests); a scratch test against the real en-us.yaml fails on the source labels, then removed.
CI: final-attempt failures over 13 runs.
Coverage grid: 11 files × 7 dimensions; findings in correctness (spec, TokenUsage, composable), errors (null as 0), i18n (source keys), a11y (name), conventions (unused emit and prop), tests (no fetchUsage test).
Not checked: planning mode, an error mid-message, UI Tools off, stopping a stream, real sub-agents; each needs a mock or settings change on torchiaf's environment.
CI
e2e is red with two final failures; i18n, lint and unit tests pass. The token-usage spec is this PR (finding 1). The scroll test also fails on main, so it isn't.
Run
Commit
Token usage spec
Scroll test (expand/collapse planning)
43834164964
79968cc (this PR)
fails 3/3, label " 0 "
fails 3/3
43471969845
fd493f1 (this PR)
fails 3/3
passes
42833645669
28ae86d (main, push)
not in main
fails 3/3
42831302124
3593589 (main, push)
not in main
fails 3/3
43104450587
Dependabot
not in main
fails 3/3
Checked, and not checked
Live on the PR preview against 13.62, both passes, as admin, every chat prefixed probe346, demo346 or passB346. No llm-mock queue, agent setting or cluster object was changed.
Every finding above was re-checked at 79968cc; the 500 case and the agent route were re-run by me after the passes.
Unit tests (both touched suites) and the CI logs; Cypress not run, per policy.
Not checked:
Planning mode, an error mid-message, UI Tools off, stopping a streaming answer, real sub-agent attribution: each needs a queued mock or a settings change on torchiaf's live environment.
The Figma frame (token expired) and screen readers beyond the AX tree.
What I'd post
In your shape: a short intro, one inline per point, no code, no fix, no preview link. Comments 5 to 7 are the optional nits; drop them if you want it lighter. The two screenshots go in as attachments when posting. Before/after demo videos are on this page if you want them in the body.
Review body (Comment)
I tried it on a running build against an agent with rancher/rancher-ai-agent#507: the count, the popover, new chat, history and reopening the panel all work and match the API. A few points inline. The other red e2e (scroll handling) fails on main too, so it isn't this PR.
This spec can't pass until rancher/rancher-ai-agent#507 is merged: CI deploys agent main, which has no usage endpoint, so the label stays at 0 on all three attempts. The exact counts are also llm-mock's estimate of each request's size, so a later prompt or MCP tool change in the agent repo will fail it again.
A failed usage request lands here as null, so the footer drops to "Tokens used: 0" and disables the button, even right after it showed 1.8K (a 500 on the refresh). Against an agent without the endpoint it reads 0 for the whole chat, which looks like nothing was spent rather than unknown.

[screenshot: the footer after a 500 on the refresh]
These keys aren't in en-us.yaml, so By Source always shows the raw values: ui-tools, agent, planner, summarization. The unit test mocks the planner key, so it doesn't catch it.

[screenshot: the popover after one prompt]
The button's accessible name is only "1.8K in total": "Tokens used:" is a separate span, so tabbing to it announces a number with a menu popup and nothing about tokens.